Storage-level corruption guard

One of the many gems in Veeam Backup & Replication v9 is the introduction of storage-level corruption guard for primary backup jobs. This was already a feature for backup copy jobs. But now we have the option of periodically scanning or backup files for storage issues.It works like this: if any corrupt data blocks are found the correct ones are retrieved from the primary storage and auto healed. Ever bigger disks, vast amounts of storage and huge amounts of data mean more chances of bit rot. It’s an industry wide issue. Microsoft tries to address this with ReFS and storage space for example where you also see an auto healing mechanism based on retrieving the needed data from the redundant copies.

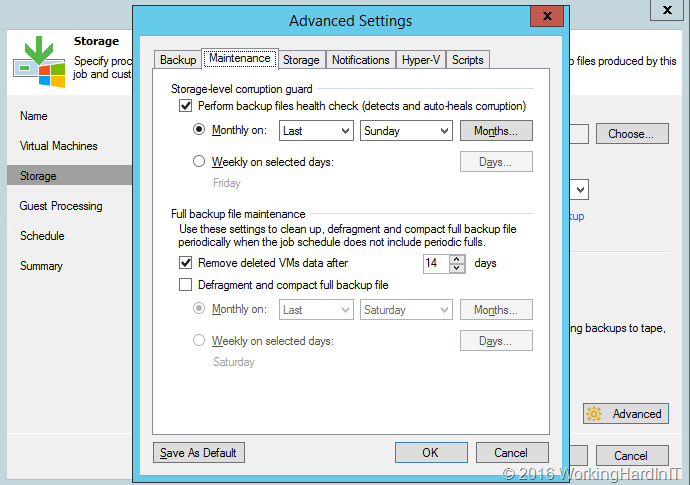
We find this option on the maintenance tab of the advanced setting for the storage settings of a backup job, where you can enable it and set a schedule.
image

The idea behind this is that this is more efficient than doing periodical active full backups to protect against data corruption. You can reduce them in frequency or, perhaps better, get rid of those altogether.

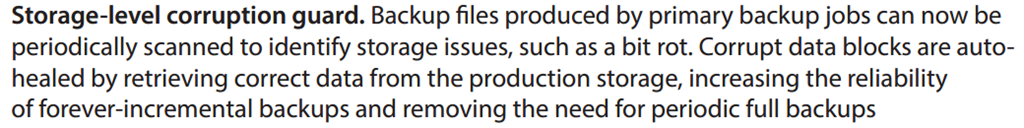
Veeam describes Storage-level corruption guard as follows:
image

Can it replace any form of full backup completely? I don’t think so. The optimal use case seems to lie in the combination of storage-level corruption guard with periodic synthetic backups. Here’s why. When the bit rot is in older data that can no longer be found in the production storage, it could fail at doing something about it, as the correct data is no longer to be found there. So we’ll have to weigh the frequency of these corruption guard scans to determine what reduction if making full backups is wise for our environment and needs. The most interesting scenario to deal with this seems to be the one where we indeed can eliminate periodic full backups all together. To mitigate the potential issue of not being able to recover, which we described above, we’d still create synthetic full backups periodically in combination with the Storage-level corruption guard option enabled. Doing this gives us the following benefits:

  • We protect our backup against corruption, bit rot etc.
  • We avoid making periodic full backups which are the most expensive in storage space, I/O and time.
  • We avoid having no useful backup let in the scenario where Storage-level corruption guard needs to retrieve data from the primary storage that is no longer there.

To me this seems to be a very interesting scenario. To optimize backup times and economies. In the end it’s all about weighing risks versus cost and effort. Storage-level corruption guard gives us yet another tool to strike a better balance between those two. I have enabled it on a number of the jobs to see how it does in real life. So far things have been working out well.
Azure AD Connect 1.1.105.0 is GA

On February 18th  2016 Microsoft released a significant update to Azure AD Connect, version 1.1.105.0. It adds some capabilities and improves on others. For me this is a core piece of the puzzle today and in the future for many of my plans to optimize the future IT Infrastructure & DevOps. Even when politics seem hell bound on slowing you down and cause a serious delay and missed opportunities this piece of technology is key in breaking through those barriers and keep moving ahead.

So what’s in the box with version  1.1.105.0

  • Automatic upgrade feature for Express settings customers.
    Support for the global admin using MFA and PIM in the installation wizard.
  • We can change the user’s sign-in method after initial install.
  • We can now set Domain and OU filtering in the installation wizard. As a secondary benefit this means we can now connect to forests where not all domains are available.
  • We get a Scheduler is built-in to the sync engine.

Some preview features are now GA:

We get one new preview features which is going to be a hit in world where patience disappeared from the equation:

  • The default sync interval is now 30 minutes instead of 3 hours before. this is configurable now in the scheduler.

It also fixes the following issues:

  • The verify DNS domains page didn’t always recognize the domains.
  • Prompts for domain admin credentials when configuring ADFS.
  • On-premises AD accounts are not recognized by the installation wizard when they are in a domain with a different DNS tree than the root domain.

Grab the latest version of Azure AD Connect here.

Dell Compellent SCOS 6.7 ODX Bug Heads Up

UPDATE 3: Bad and disappointing news. After update 2 we’ve seen DELL change the CSTA (CoPilot Services Technical Alert)  on the customer website to “’will be fixed” in a future version. No according to the latest comment on this blog post that would be In Q1 2017. Basically this is unacceptable and it’s a shame to see a SAN that was one of the best when in comes to Hyper-V Support in Windows Server 2012 / 2012 R2 decline in this way. If  7.x is required for Windows Server 2016 Support this is pretty bad as it means early adopters are stuck or we’ll have to find an recommend another solution. This is not a good day for Dell storage.

UPDATE 2: As you can read in the comments below people are still having issues. Do NOT just update without checking everything.

UPDATE: This issue has been resolved in Storage Center 6.7.10 and 7.Ximage

If you have 6.7.x below 6.7.10 it’s time to think about moving to 6.7.10!

No vendor is exempt form errors, issues, mistakes and trouble with advances features and unfortunately Dell Compellent has issues with Windows Server 2012 (R2) ODX in the current release of SCOS 6.7. Bar a performance issue in a 6.4 version they had very good track record in regards to ODX, UNMAP, … so far. But no matter how good your are, bad things can happen.

DellCompellentModern

I’ve had to people who were bitten by it contact me. The issue is described below.

In SCOS 6.7 an issue has been determined when the ODX driver in Windows Server 2012 requests an Extended Copy between a source volume which is unknown to the Storage Center and a volume which is presented from the Storage Center. When this occurs the Storage Center does not respond with the correct ODX failure code. This results in the Windows Server 2012 not correctly recognizing that the source volume is unknown to the Storage Center. Without the failure code Windows will continually retry the same request which will fail. Due to the large number of failed requests, MPIO will mark the path as down. Performing ODX operations between Storage Center volumes will work and is not exposed to this issue.

You might think that this is not a problem as you might only use Compellent storage but think again. Local disks on the hosts where data is stored temporarily and external storage you use to transport data in and out of your datacenter, or copy backups to are all use cases we can encounter.  When ODX is enabled, it is by default on Windows 2012(R2), the file system will try to use it and when that fails use normal (non ODX) operations. All of this is transparent to the users. Now MPIO will mark the Compellent path as down. Ouch. I will not risk that. Any IO between an non Compellent LUN and a Compellent LUN might cause this to happen.

The only workaround for now is to disable ODX on all your hosts. To me that’s unacceptable and I will not be upgrading to 6.7 for now. We rely on ODX to gain performance benefits at both the physical and virtual layer. We even have our SMB 3 capable clients in the branch offices leverage ODX to avoid costly data copies to our clustered Transparent Failover File Servers.

When a version arrives that fix the issue I’Il testing even more elaborate than before. We’ve come to pay attention to performance issues or data corruption with many vendors, models and releases but this MPIO issue is a new one for me.